> ## Documentation Index
> Fetch the complete documentation index at: https://docs.famulor.io/llms.txt
> Use this file to discover all available pages before exploring further.
# Models & voices
> Choose models, preview voices, clone your own, and turn on reliable fallbacks
Famulor selects the models used to understand and answer calls. You choose voices, languages and speaking controls. The **Fallbacks & Guardrails** add-on also enables compatible model choices for your workspace.
The model picker and your assistant's selected model names are visible only when **Fallbacks & Guardrails** is available in the active workspace. This rule applies to the dashboard, REST API and MCP; Whitelabel access alone does not grant model access. Without this add-on, the models selected automatically for your assistant are not shown. Voice selection and language controls remain available according to your plan.
## Model catalog
The assistant editor shows a curated catalog of models available to your workspace:
| Type | Purpose |
| - | - |
| Language model | Understands the conversation and decides what to say or do |
| Speech recognition | Converts the caller's speech into text |
| Text-to-speech | Produces the assistant's spoken voice |
| Realtime | Listens and speaks in one low-latency model |
Availability depends on your workspace and selected [engine mode](/assistants/engine-modes).
When **Fallbacks & Guardrails** is included, you can choose models separately for pipeline, realtime, and half-cascade assistants. Otherwise, the assistant uses the recommended automatic selection.
See [AI regions & models](/settings/ai-regions) for the complete model list, EU/US endpoint availability, automatic SIP routing and infrastructure locations.
## Temperature
In Pipeline mode, **Temperature** controls how closely the language model sticks to your prompt versus varying its wording. The slider runs from 0 — deterministic and on-script — upward to more creative, improvised replies. **0.5–0.8** is a typical range for phone conversations.
Treat it as final fine-tuning, not a substitute for a well-written prompt:
1. Finish the prompt first — role, goals, boundaries, tone.
2. Start low.
3. Raise it in small steps, only once the baseline sounds good.
4. Test and compare after each change.
Raise it when replies sound stiff or formulaic and the use case tolerates some improvisation. Keep it low when consistency, compliance, or precise wording matter more than natural variation.
## Voice library
Use the voice picker to filter by language and voice characteristics, then play a sample before saving.
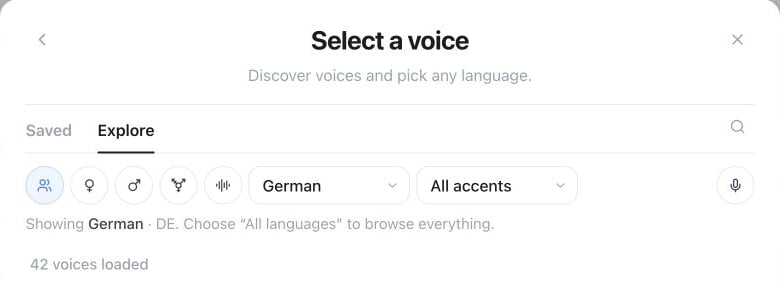 The public REST endpoint `GET /api/v1/voices` and MCP tool `get_voices` return provider-neutral local selectors. Upstream voice IDs and supplier names are not exposed; pass the returned `id` directly as `tts_voice`.
* **Assistant voice** — the default voice for the assistant.
* **Voice per flow agent** — give individual [flow](/flow-builder/nodes) agents distinct voices.
* **Voice per language** — change the voice together with [automatic language switching](/assistants/languages).
* **Cloned voices** — when included in your plan, add a private custom voice and use it like a library voice.
When recording a sample to clone, use clear, high-quality audio with steady, natural delivery and no background noise — and only clone a voice you have permission to use (see [Voice cloning consent](/assistants/voice-cloning-consent)).
For API cloning, check `sample_constraints` from `GET /api/v1/voices/clone/capability` for how many samples are currently accepted (`max_files`, up to 3), the maximum size per sample (`max_bytes_per_file`), and the maximum sample length (`max_duration_seconds`, or `null` for no limit), prepare that many direct uploads with `POST /api/v1/voices/clone/uploads`, upload the samples, then submit the job with `POST /api/v1/voices/clone`. MCP offers the equivalent `get_voice_clone_capability`, `create_voice_clone_upload`, and `submit_voice_clone` tools. The dashboard, REST, and MCP paths share the same **Clone your own voice** entitlement, consent check, creation pricing, and tenant isolation.
## Speaking style
The available controls adapt to the selected model. Depending on the voice, you may see:
* speaking rate and output volume;
* stability, similarity, or expressiveness;
* free-text style instructions;
* a pronunciation dictionary for names, abbreviations, and specialist terms;
* filters that prevent markdown and emoji from being read aloud.
Only compatible controls are shown and applied.
Pick the voice first, then tune one control at a time — stability, similarity, or rate — and listen to a realistic phrase from your actual call flow before changing the next one.
When the **Dynamic emotions** setting (Expressive Mode) is available for the selected voice, the assistant can adapt emotion, pacing, emphasis, pauses, and supported non-verbal sounds to the conversation. It applies to pipeline and half-cascade assistants; realtime speech models handle vocal expression natively. Availability depends on the selected voice, and unsupported delivery cues are not applied. Transcripts remain clean and do not include delivery markup.
## Speech recognition glossary
Open **Assistant settings → Voice → Speech recognition** to add customer, product, and proper names that should be transcribed accurately. The glossary affects the transcript; use the pronunciation dictionary separately when a term also needs a special spoken form.
If **Automatic term detection (Beta)** is available and enabled, the assistant can recognise additional terms for the current call. This may add AI usage. Detected terms are not added to your saved glossary.
## Fallback chains
**Fallback chains** is a single switch, not a set of choices you configure. Turn it on, and if the primary speech-recognition, language-model, or voice service times out, errors, or drops mid-call, the assistant automatically moves to a compatible backup so the conversation keeps going instead of dropping. Famulor selects and maintains which backup each chain falls through to — there's no picker for the backup models themselves.
Fallback chains ship with the **Fallbacks & Guardrails** add-on; check **Settings → Plan** for availability. Failing over doesn't add a separate charge on its own — a call that fails over still bills at the normal call-minute rate.
Test important assistants after changing models, voices, or languages. A short simulation is usually enough to catch pronunciation and timing differences.
## Saved announcements
Prepare and preview each fixed announcement using compact icons inside its text field:
* **Greeting** on the assistant’s main page: the greeting and any enabled static message after silence.
* **Assistant settings → Privacy → Consent**: the consent message.
* The **end-call tool editor**: that action’s farewell message.
When secondary languages are configured, the farewell text stays editable and guides a message generated in the caller’s current supported language. These farewells do not use saved audio; preparation skips them. Greetings and consent keep their existing preparation behavior. Without secondary languages, farewells keep their existing delivery behavior, including supported saved audio.
Use the **Play**, **Stop** and **Generate audio** icons inside the relevant field. A tooltip shows the preparation status and recording duration when available. Generation uses the saved settings, so save draft changes first.
Saving requests preparation in the background. A compact animated dialog confirms your save, and you can continue editing immediately afterward. Preparation details remain beside each message, without interrupting your work. Matching audio is reused. Changing a message, voice, language or relevant speaking settings requires a matching recording before that audio can be used again.
The preparation keeps the selected engine’s supported voice. Full Duplex uses its native voice; **Fallback settings** applies only if the conversation switches to Pipeline. Uploaded greetings retain their recorded voice. Caller-specific variables, dynamic messages, unsupported modes and unsuccessful preparation keep their existing call behavior. A caller-first greeting still waits for the caller; eligible fixed messages after silence are prepared separately.
Preparation does not prove that a consent message was heard or accepted. Consent is still checked during each call, including complete playback where required.
REST supports `GET /api/v1/assistants/{id}/announcements`, `POST` on the same path, and the authenticated audio link returned for a ready item. MCP and Milian provide `get_assistant_announcements` and `prepare_assistant_announcements`. Audio previews are private to the workspace.
## Voice creation and credits
Voice cloning is a plan feature. Open **Clone a voice** directly; the creation button shows **Create · free** while your allowance remains, then **Create + X credits**. The charge is made once for a successful creation. Stored voices have no plan capacity limit or recurring storage charge.
Send `expected_credits` with `POST /api/v1/voices/clone` or `submit_voice_clone`, using the displayed `pricing.next_creation_credits` from the capability response. Set it to `0` to accept only a free creation. If the price increases or the last free creation is used elsewhere, refresh the price and confirm again. Retry the same job ID after an interrupted request; a successful job is charged only once. The legacy `clone_voice` tool also requires `expected_credits`.
This documentation is built and hosted on [Mintlify](https://mintlify.com), a developer documentation platform.